Door categorieën bladeren
Ontdekken
Fiverr Pro
Nederlands
$
USD


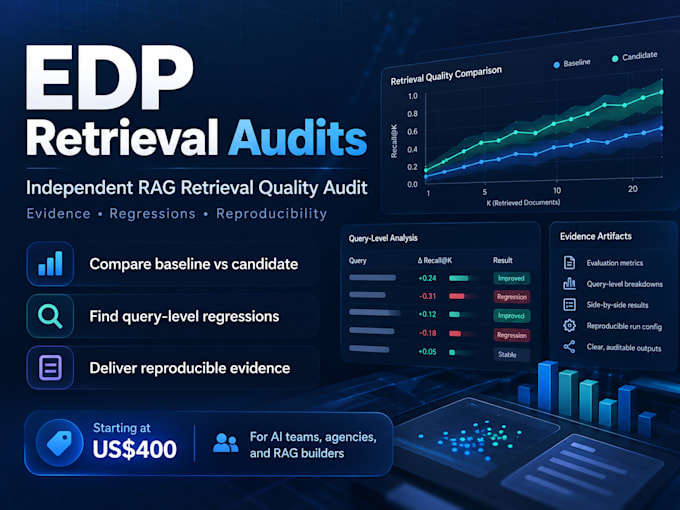
Is your RAG pipeline returning worse results after an embedding, reranking, or retrieval change?
I provide independent, reproducible RAG retrieval quality audits for AI teams and agencies.
For up to 30 queries and two comparable retrieval configurations, I analyze baseline vs. candidate rankings, identify query-level regressions and recoveries, and investigate missing or displaced evidence.
You receive a technical report, machine-readable findings, and reproducibility details.
My public audits include RouteMind and DPOLens. In RouteMind, I identified 15 scoring discrepancies across 1,400 query/arm results. The maintainer independently reproduced the findings and corrected the benchmark.
Required inputs include a fixed query set, relevance judgments or expected evidence, and compatible retrieval exports.
This service does not include implementing code fixes or evaluating generated answer quality.
Please contact me before ordering to confirm compatibility and scope.
RAG Retrieval and Evaluation Specialist
Talen
What do I need to provide?
A fixed query set, baseline and candidate retrieval results, expected evidence or relevance judgments, and relevant pipeline configuration details. Sanitized exports are preferred. We confirm compatibility before the audit begins.
Do you need access to my infrastructure?
No. This audit is designed to work with compatible offline exports. I do not require production credentials, private API keys, or direct access to your servers.
Will you fix my RAG pipeline?
This service provides independent technical analysis, reproducible findings, and recommendations. Implementation of fixes, model tuning, and full RAG development are not included.
Do you have examples of previous audits?
Yes. My public portfolio includes independent audits of RouteMind and DPOLens. The RouteMind maintainer independently reproduced 15 identified scoring discrepancies and incorporated benchmark corrections. These were public beta audits, not paid client engagements.