Door categorieën bladeren
Nederlands
$
USD
Koppel je AI aan Fiverr
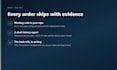
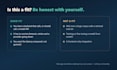
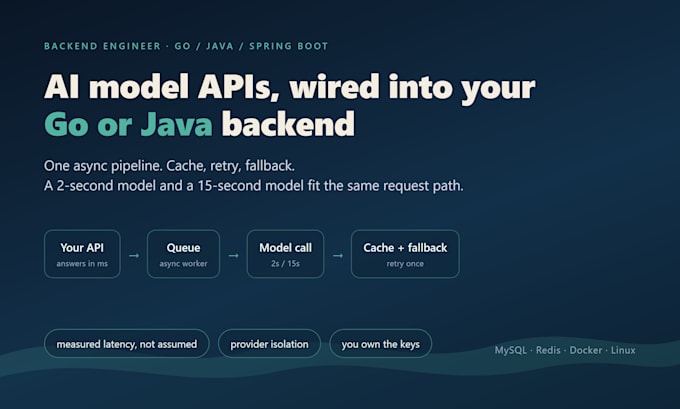
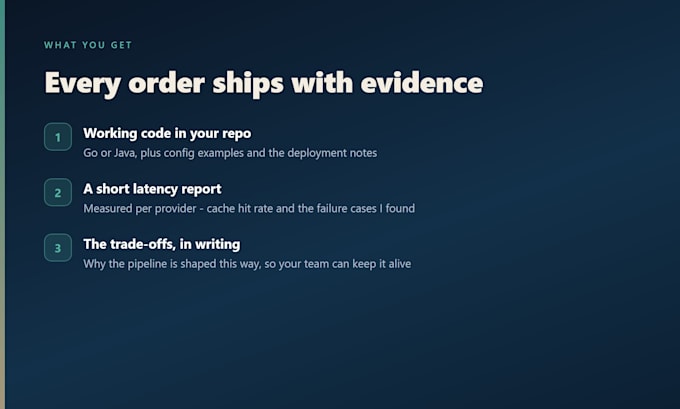
You want an AI feature inside your backend that survives real users - not a demo notebook. I'm a backend engineer (Go / Java / Spring Boot). I built the production version: three models behind ONE async pipeline, a cache in front of them, and a provider interface thin enough that swapping vendors is config-only. What I do: - Model APIs behind one async pipeline: a 2s model and a 15s model fit the same path, and the page never waits - Cache + retry + fallback: retry once, then the next provider - Provider isolation: one interface, one adapter per vendor, no vendor SDK in your domain code - Latency budget made explicit: measured, not assumed What you get: - Working code in your repo (Go or Java), plus config examples - A short report: measured latency per provider, cache hit rate, failure cases - Deployment notes and the trade-offs, in writing What I need: - Where the code lives and how it deploys - Which providers you use, and the API keys (yours - you own the spend) - One good output and one bad output; worth more than a spec Not a fit if you need a model trained from scratch, RAG over a large corpus, or a frontend-only integration. Message me first.
Backend Engineer
Talen
Do you use RAG or vector databases?
Not in this gig. I integrate model APIs defensively: one async pipeline, one provider interface, plus cache, retry and fallback. If you need retrieval over a large corpus with an eval set, that is a different scope and I will say so honestly.
Who provides the AI API keys?
You do - you own the account and the spend. I wire the integration and keep keys in config or a secret store, never hardcoded in the repo.
Which languages and frameworks do you work in?
Go and Java (Spring Boot) for the backend, plus MySQL, Redis, Docker and Linux in production. Frontend work is not what this gig is for.
Can you guarantee the model output quality?
No, and I will not pretend to. I make the pipeline reliable and measurable: timeouts, retry, fallback, cached calls and a real latency number per provider. Output quality is a prompt and provider problem we tune together.