Door categorieën bladeren
Ontdekken
Fiverr Pro
Nederlands
$
USD

If your OpenAI, Claude or Gemini bill keeps growing faster than your usage, money is usually being wasted. The common causes are long prompts sent in full every time, simple tasks running on the biggest model, and work that could wait being paid for at full price.
I'm a developer with 3 years of experience building AI apps. I read your code and usage data, find where the money goes, and fix the biggest leaks first.
What I look at
- Prompt caching, which providers bill at a fraction of the normal input price
- Batch APIs for work that doesn't need an instant answer, at about half price
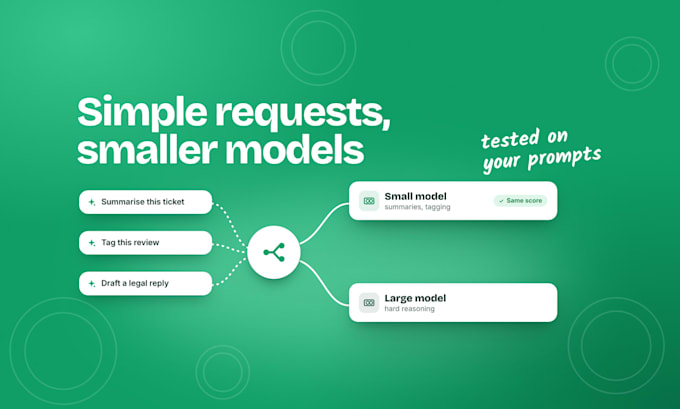
- Routing simple requests to smaller, cheaper models, tested on your own prompts so quality holds
- Trimming context, chat history and retrieved chunks
- Response caching, retries and runaway loops
- Budgets, alerts and a dashboard so the bill can't surprise you
You get a report that ranks each saving by size and effort, with before and after numbers for every fix I make.
I can't promise a percentage before I've seen your usage. After the audit you'll know the expected saving.
Send me your monthly spend, the providers you use and what your app does with AI.
arehman
Talen
How much can you save me?
It depends on how your app uses the API. I won't guess a percentage before the audit; the report gives an estimate for each fix so you can decide what's worth doing.
Is it worth it for a small bill?
Usually once you spend a few hundred dollars a month. Below that, the audit may cost more than it saves, and I'll tell you so before you order.
What access do you need?
Read access to the repo, plus a usage export or dashboard screenshots from your provider. Basic needs no production keys; I work from samples and logs.
Will cheaper models hurt quality?
Not if they're tested. I run your real prompts through both models and only switch the requests where the cheaper one scores the same.
Which providers do you work with?
OpenAI, Anthropic Claude, Google Gemini and OpenRouter, plus LiteLLM as a gateway in front of any of them.
Will you change my production app?
Only on Standard and Premium, through pull requests you review and merge. I test each change on staging first.
Do you sign an NDA?
Yes, if you need one. I keep your data only for the length of the order.