Door categorieën bladeren
Ontdekken
Fiverr Pro
Nederlands
$
USD

Level 1
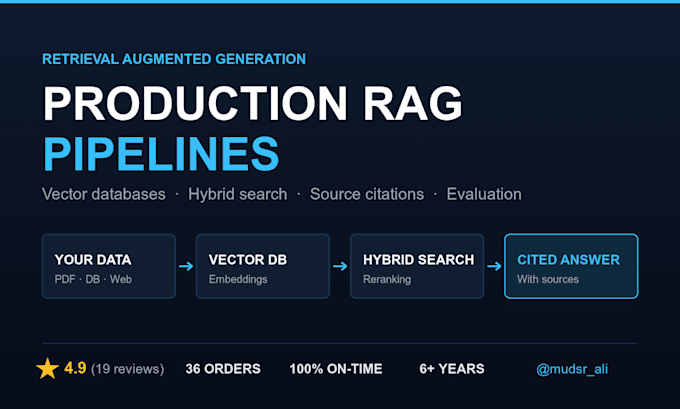
Need a RAG chatbot or retrieval pipeline that does more than simply send documents to an LLM?
I build custom Retrieval-Augmented Generation (RAG) systems that retrieve relevant information from your data and use it to generate context-aware answers.
What I can build:
Technology stack: Python, FastAPI, LangChain or LlamaIndex where appropriate, PostgreSQL/pgvector, Qdrant, Chroma, and other compatible vector stores.
I can help you build a new RAG pipeline, improve an existing implementation, or integrate retrieval into your application.
Every project has different data, quality requirements, and infrastructure constraints. Please message me with your use case, data sources, and expected outcome before ordering so we can agree on the right scope.
Senior Software Engineer, SaaS, Backend, Cloud, Ai
Level 1
Talen
Which package fits my project?
Tell me roughly how much content you have and where it lives. Starter suits a single source under 500 pages. Production suits a full corpus where answer accuracy matters. Platform suits multiple systems that keep changing.
Which vector database do you use?
Whichever fits your case: Pinecone, Qdrant, Weaviate, Chroma or pgvector. If you already run PostgreSQL, pgvector often avoids a new service and cost entirely. I recommend based on scale and budget, not preference.
How accurate will the answers be?
I will not promise a number before seeing your data. What I do promise is measurement: Standard and Premium include an evaluation set so you see retrieval accuracy as a figure, and every answer carries citations so wrong output is traceable.
Who pays for the OpenAI or Claude API usage?
You do, on your own accounts, so you keep control and full visibility of spend. Embedding and query costs are the two drivers. I estimate your realistic monthly cost before we start and build in caching and token limits to keep it down.
Is my data kept private?
Everything runs on your own infrastructure and provider accounts. I use API endpoints that do not train on your data, and I will sign an NDA. If your documents cannot leave your servers at all, I can build fully self-hosted with open models.
What do you need from me to start?
A sample of your documents or database access, 10 to 20 example questions users will ask, and your provider API key. The example questions matter most: they become the evaluation set I tune retrieval against.
