Door categorieën bladeren
Nederlands
$
USD
Maak verbinding met je AI
Python and Data Engineer Web Scraping ETL Pipelines SQL AI Video Genrator
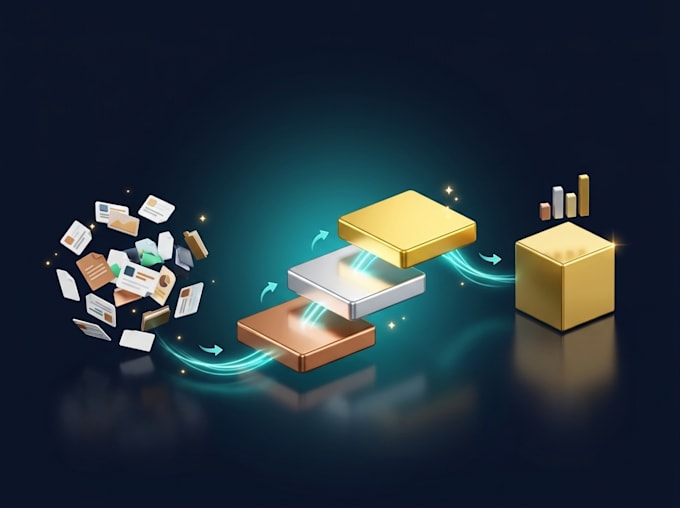
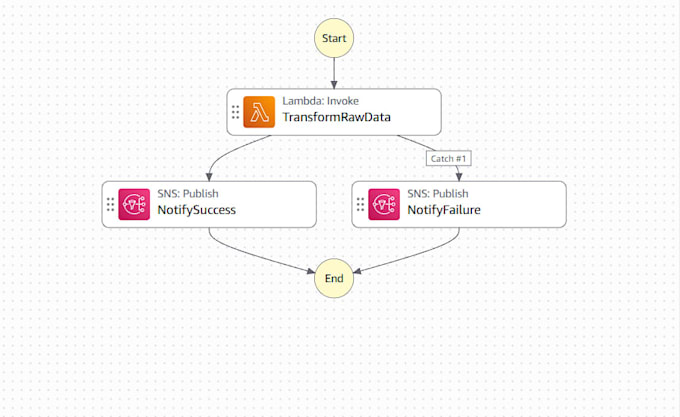
Have raw data stuck in CSV files, APIs or messy tables? I'll turn it into clean, analytics-ready tables using Databricks, PySpark and Delta Lake with the Medallion (Bronze, Silver, Gold) architecture.
What you get:
Bronze layer: raw data ingested safely, nothing lost
Silver layer: cleaned, deduplicated and standardized data
Gold layer: business-ready tables for reports and dashboards
Well-commented PySpark and SQL notebooks
Data quality checks (nulls, duplicates, wrong formats)
Simple documentation so your team can maintain it
My proof: I built an end-to-end Databricks project that processed over 51,000 records through all three Medallion layers. I'm a micro1 Certified Data Engineer with Cloud Data Engineer training (Python, SQL, AWS, Snowflake, Spark).
Note: the pipeline runs in YOUR Databricks workspace so you own your data. A free Databricks account is enough for small projects.
Message me before ordering with your data source and goal, and I'll recommend the right package.

Do I need a paid Databricks account?
No. A free account is enough for small projects. Larger workloads may need a paid workspace in your name.
Can you improve my existing notebooks?
Yes. Send me the details and I’ll make a custom offer.
Will I understand how it works?
Yes. Notebooks are commented, and Premium includes a walk through .