Door categorieën bladeren
Ontdekken
Fiverr Pro
Nederlands
$
USD

Automatische vertaling
Beschrijving:
Een LLM-functie uitrollen zonder een evaluatieset is blind verpakken. Ik ontwerp en bouw evaluatiepijplijnen die je met cijfers vertellen of je prompts, model of RAG-configuratie echt beter zijn geworden voordat jouw gebruikers dat merken.
Wat je krijgt:
Neem contact met mij op voordat je een fout plaatst.
LLM AI Model Evaluation Specialist , QA automation Architect ,Eval pipelines
Talen
Automatische vertaling
Automatische vertaling
Moet ik mijn productiegegevens delen?
Nee. Ik werk met monsters die jij kiest, synthetische data of een geredigeerde export. Alles blijft onder jouw NDA en wordt bij levering verwijderd.
Welke evaluatietools gebruik je?
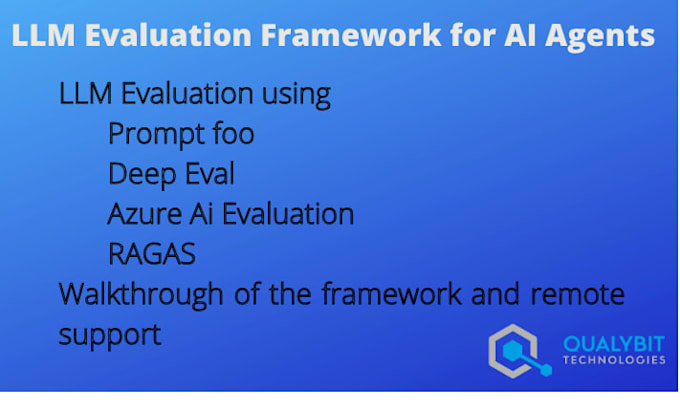
Welke evaluatietools gebruik je? Promptfoo, LangSmith, Ragas, DeepEval, of een gewone Python/pytest-harnas. Ik kies wat bij jouw stack past; de code blijft van jou.
Kun je een RAG-systeem of een agent evalueren, niet alleen een enkele prompt?
Ja. Voor RAG beoordeel ik retrieval en generatie apart (contextuele precisie/herinnering, betrouwbaarheid, relevantie van het antwoord). Voor agents beoordeel ik de correctheid van tool-aanroepen en taakafronding.
Wat betekent "LLM-as-judge" en is het betrouwbaar?
Een tweede model beoordeelt outputs volgens een rubric die ik met jou opzet. Ik calibrateer het aan een door mensen gelabelde steekproef zodat je weet hoeveel je op de scores kunt vertrouwen.
Doe je ook aan red-teaming of modelvergelijking?
Ja — beide gigs staan apart op mijn profiel, of voeg ze hier als extras toe.