Sommige informatie wordt in het Engels weergegeven.
Over mij
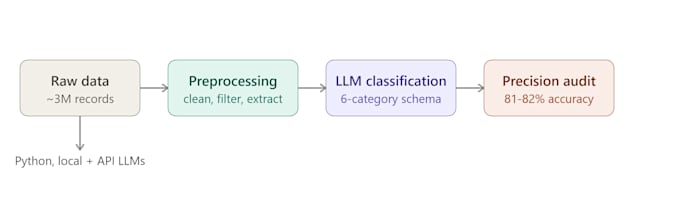
I build and run text classification pipelines using large language models and Python — including a project analyzing ~3 million unstructured text records with a locally deployed Llama 3.1 8B model. I help clients turn messy, unlabeled text data into clean, structured categories they can actually use, whether that's for content moderation, sentiment analysis, survey coding, or research data processing.
I communicate clearly, deliver documented work, and treat accuracy as seriously as speed.... Lees meer