Door categorieën bladeren
Ontdekken
Fiverr Pro
Nederlands
$
USD

Machine Learning Enigneer
Skills
Bekijk mijn diensten

Machine Learning Intern
Indsac • Fulltime
Feb 2026 - Present • 7 mos
Engineered an AI-based surveillance system for real-time visitor monitoring and security automation, reducing manual security check load by ~60% across 4 active CCTV feeds. Built a face recognition pipeline using HuggingFace FaceNet embeddings and FAISS vector indexing, achieving sub-100ms identity matching for 500+ profiles. Developed a real-time video pipeline in OpenCV to detect, track, and capture snapshots at 25 fps, handling concurrent streams without frame drops. Designed an automated alert engine flagging unrecognized individuals within 3 seconds, integrated with SMS and email notifications. Developed a Flask-based web application for visitor approval, access logs, and system monitoring; containerized using Docker.
Machine Learning Research Intern
Suvidha Foundation • Fulltime
Dec 2025 - Feb 2026 • 2 mos
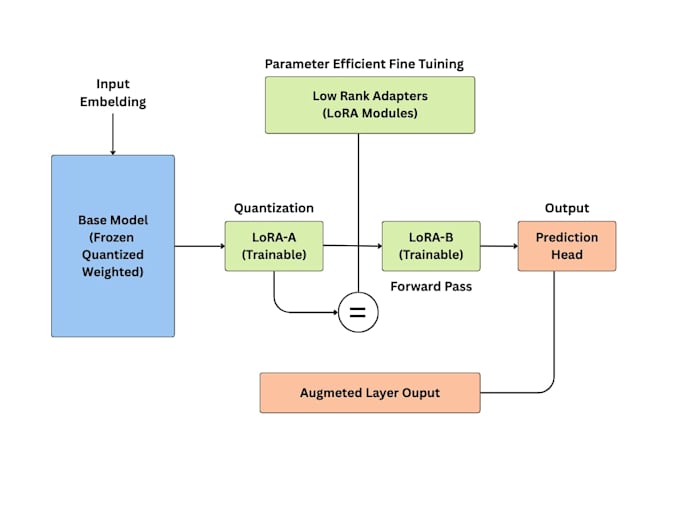
Researched multi-document summarization for Indian English using LLMs; surveyed 15+ architectures (T5, BART, PEGASUS, LLaMA) to inform model selection. Fine-tuned Llama 3-3B using QLoRA (4-bit) via HuggingFace PEFT library, achieving ROUGE-1 49.06, outperforming PEGASUS baseline by 6.2 points. Designed 4-bit quantization pipeline enabling large-model fine-tuning on a single T4 GPU, cutting memory usage ~40% vs full fine-tuning. Benchmarked LoRA vs QLoRA across speed, memory, and ROUGE metrics; QLoRA delivered 3x lower compute vs full fine-tuning; tracked experiments using MLflow.
